The type of server you need to run a large language model (LLM) depends on the model size, workload, number of users, and performance goals. A small, pre-trained model may run on a CPU-based server, while larger models often need a GPU-powered AI server with high memory capacity and fast storage.
Before choosing a server, decide whether you want to run an existing model, fine-tune it with your own data, or train a model from scratch.
According to Gartner’s June 2026 forecast, AI-optimized servers are expected to account for 31% of global data center electricity consumption in 2026.
This highlights the growing computing demands of AI. Before buying a server, compare your workload, hardware needs, and long-term costs.
Now, read further below to learn what kind of server you need to run an LLM model.
Which Server Is Best for Running a Large Language Model?
A GPU-powered AI server is a strong choice for running large language models, especially when you need fast responses, support for multiple users, or high-volume AI processing. However, a CPU-based server can also run some smaller or quantized models, depending on the model’s memory needs and expected performance.
Here are the main options:
- GPU server: Best for demanding LLM inference, fine-tuning, and model training.
- CPU-based server: Suitable for some smaller models, low-volume workloads, and cost-conscious deployments.
- AI server cluster: Useful for large models and workloads that require multiple GPUs or servers working together.
- Cloud-based server: A flexible option for testing models or accessing computing resources without buying physical hardware.
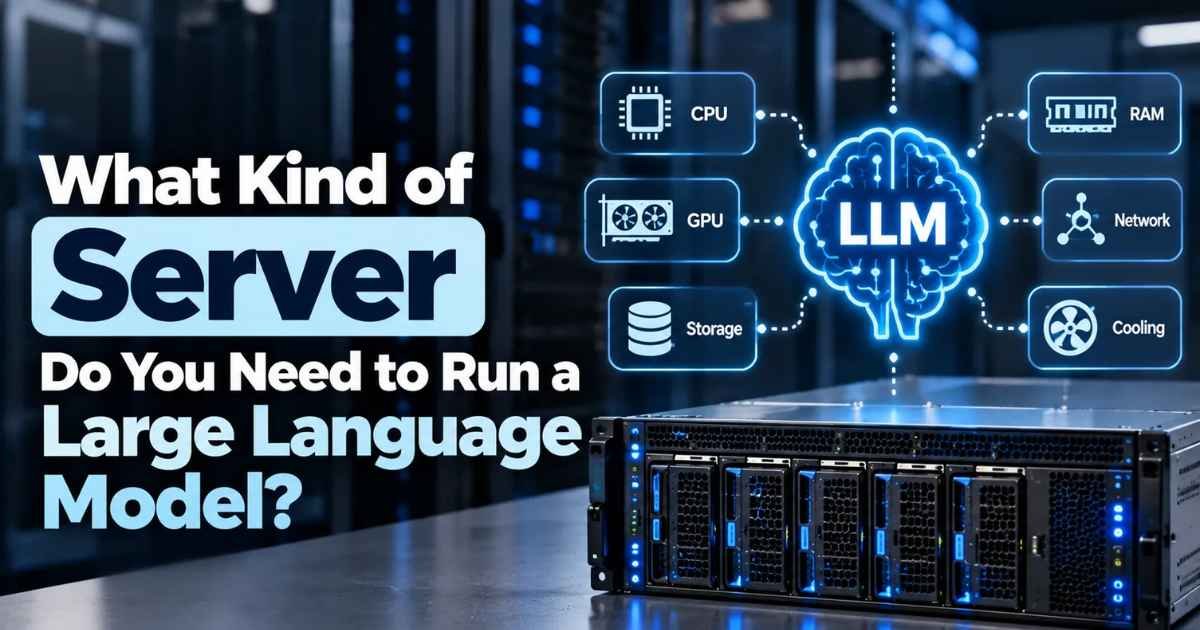
What Hardware Does an LLM Server Need?
The server’s components affect how quickly it processes information and generates answers. Check these five areas before you buy.
1. GPUs for Faster AI Processing
A graphics processing unit (GPU) handles many calculations at the same time. This makes it useful for AI tasks that need heavy computing power.
When comparing GPU servers, check:
- GPU memory capacity.
- Number of supported GPUs.
- Compatibility with your chosen AI software.
- Power use and cooling needs.
A small model may run on a single suitable GPU. Larger models may need several GPUs or a system with enough combined memory to hold the model.
2. RAM and GPU Memory for Large Models
Memory stores the information a model needs while it works. If the model does not fit into available memory, the server may run slowly or fail to load it.
GPU memory, also called VRAM, is especially important for fast AI processing. System RAM also helps with data handling and other server tasks.
Choose memory based on the model’s size, precision, context length, and number of users. Quantization, which reduces the number of bits used to represent model values, can lower memory needs.
3. CPU, Storage, and Networking
The CPU manages general computing tasks and supports the GPUs. Choose a modern server processor that can handle your workload without creating a bottleneck.
Also look for:
- Fast SSD or NVMe storage: Helps load model files and process datasets.
- Enough storage space: Holds models, business data, logs, and backups.
- Fast networking: Helps multiple GPUs and servers exchange data.
- Expansion options: Allow you to add storage, memory, or processing power later.
These features matter even more when you plan to run AI applications for a growing team.
Should You Buy a GPU Server or a Standard Server?
A standard server can work for smaller language models, testing, and light workloads. However, a GPU server often makes a better choice for larger models, frequent requests, and demanding AI applications.
When a Standard Server Makes Sense
Consider a CPU-based server if you want to test a small model, learn how LLMs work, or handle a limited number of requests. It may also suit workloads where response speed is less important.
When a GPU Server Is Worth the Cost
Choose a GPU server when you need faster responses, larger models, or frequent AI processing. Businesses that plan to fine-tune models should also compare GPU memory, processing capacity, and software support.
According to Gartner’s May 2026 forecast, AI spending is expected to grow 47% in 2026. As companies invest in AI, choosing infrastructure that fits the workload becomes increasingly important.
How Do Your LLM Workloads Affect Server Requirements?
Running an Existing Model
If you want to use a pre-trained model for a chatbot, document search, or content generation, focus on inference requirements. A smaller model may run on a CPU server, while larger models or applications with strict response-time targets may need one or more GPUs.
Fine-Tuning an Existing Model
Fine-tuning adapts a pre-trained model to a specific task or dataset. It generally requires more computing resources than basic inference. GPU memory, processing speed, and data storage are key considerations.
Training a Model From Scratch
Training a large language model from scratch requires substantial computing power, memory, storage, and networking. Large projects may need multiple high-performance GPUs across several servers. For many businesses, using an existing model or fine-tuning one is a more practical starting point.
How Can You Choose the Right AI Server?
Before investing in hardware, assess these factors:
- Model size: Identify the model you plan to deploy and its memory requirements.
- User demand: Estimate how many people will use the application at the same time.
- Response speed: Set acceptable response times and throughput targets.
- Budget: Compare hardware, electricity, cooling, maintenance, and cloud costs.
- Data security: Decide whether your model and business data must remain on your premises.
- Scalability: Choose infrastructure that can support future growth.
For example, Lenovo offers AI infrastructure through its ThinkSystem and ThinkEdge server families for different data center and edge computing needs. Businesses can review its AI server solutions to explore potential configurations. The right model depends on the workload and required hardware specifications.
Final Thoughts
The best server for a large language model is the one that meets your model’s memory, processing, performance, and scalability requirements without unnecessary expense. Start by identifying the model and workload, then compare CPU and GPU options, memory capacity, storage, networking, and operating costs. Careful planning helps you build an AI environment that meets current needs and can grow with your business.
Disclaimer: This article is for general informational purposes only and does not constitute professional IT, engineering, or procurement advice. Server specifications, GPU memory requirements, model sizes, power and cooling demands, and costs vary by model, workload, software stack, and deployment environment, and may change without notice. The Gartner forecasts cited are third-party projections and may be revised. Readers should verify all hardware compatibility, memory requirements, power and cooling capacity, and vendor support terms directly with the manufacturer or a qualified infrastructure specialist before purchasing or deploying any server. Any mention of specific vendors or products (including Lenovo) does not imply endorsement. The author and publisher disclaim any liability for decisions made based on this content.
Get inspired by practical wisdom you can use right away—our actionable resources help you improve your day immediately.